Text to video AI is useful when you need to invent a shot rather than animate an approved photograph. Describe a visible subject, a single event, a camera position, and the intended atmosphere. Generate short shots separately, select usable intervals, then assemble them in an editor. A paragraph of plot is a planning input, not automatically a finished film.
Our original teaching example is a delivery bicycle arriving at a neighborhood repair shop with a blue parcel. We will turn that idea into three connected shots. The prompts are ready to adapt, but they are not accompanied by fabricated generation results or claims that a model followed them perfectly.
Start with a three-shot outcome
Write the ending before choosing a model: the viewer should understand that a parcel has arrived and the shop is about to open. That is enough narrative change for this exercise. We do not need a rider's backstory, a busy street, several conversations, or a dramatic transition through the building.
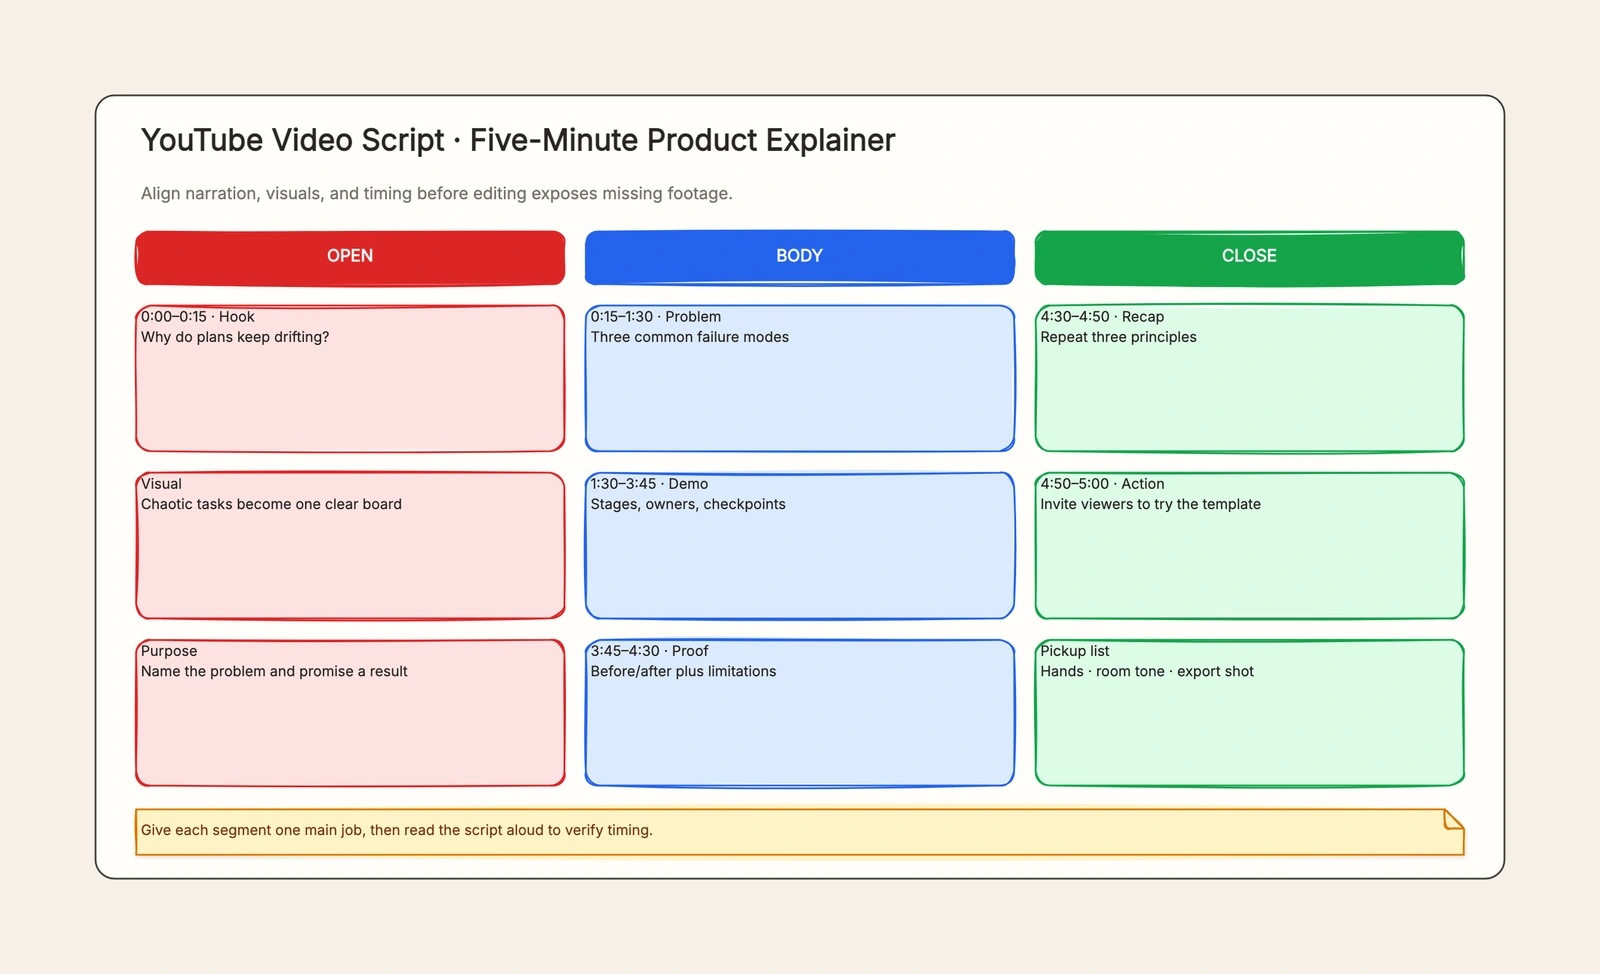
The proposed edit contains an arrival, a detail, and a reveal. Shot A establishes the bicycle outside the shop. Shot B shows the parcel resting in its basket. Shot C shows the shop door beginning to open. Each shot has a distinct job, so you can replace one without destroying the sequence.
| Shot | Information the viewer needs | Motion to request | Required continuity |
|---|---|---|---|
| A: arrival | A delivery has reached a small shop | Bicycle rolls a short distance and stops | Red bicycle, blue parcel, cream doorway |
| B: detail | The parcel is the important object | Subtle settling of parcel in basket | Same parcel color and basket material |
| C: reveal | Someone is about to receive it | Door slowly opens inward | Same doorway and direction of approach |
These are editorial targets, not guaranteed output timings. If a shot needs six seconds to read comfortably, do not compress it into two merely to match an initial plan. The script-to-storyboard process helps separate narrative decisions from generation settings.
Choose a route that accepts text as the scene input
A text-to-video mode creates the visual scene from language. An image-to-video mode starts from a picture. Some products also turn a script into stock-footage scenes, captions, and voiceover. All three may be called an AI video generator, but they solve different jobs.
For this exercise, select a model and interface that support text-led video generation. Check the current account controls before budgeting the exercise. Availability can differ between a vendor's own app, an API, and another platform hosting the model. Write down the actual model identifier or displayed version rather than the company name alone.
Runway's Gen-4.5 creation documentation describes its generation workflow. Use it to confirm the appropriate input mode and settings, not as evidence that the bicycle example has been tested. If accurate product geometry or a recurring character is essential, an approved image may be a better starting constraint; see AI image to video.
Keep aspect ratio consistent across the three shots. A vertical short needs space for the subject and any captions you will add later. Choose the composition for that format before generating, rather than treating a center crop as a harmless finishing step.
Write the first prompt as a visible event
A weak prompt reads like a synopsis:
A heartwarming cinematic story about a hardworking courier bringing hope to an old repair shop. Beautiful, emotional, highly detailed.
It names feelings but gives little direction about what appears on screen. Replace it with observable information:
Exterior of a small neighborhood repair shop with a cream doorway and a muted blue wall. A red delivery bicycle with a wicker front basket rolls a short distance into view and comes to a gentle stop beside the doorway. A small blue parcel sits securely in the basket. Medium-wide view at bicycle height, locked camera, soft overcast morning light, quiet realistic scene, one continuous shot.
The prompt specifies a location, subject, action, composition, and lighting. It asks for one change: arrival and stopping. It does not require a rider's face or a legible shop sign. Those omissions reduce unnecessary details that might become continuity problems.
Treat the first generation as a blocking rehearsal. Can a viewer identify the bicycle, parcel, and doorway? Does the stop occur inside the usable frame? If the basic event is unclear, revise that before pursuing a more elaborate visual style. The AI video prompts library provides separate patterns for camera and subject movement.
Build a continuity contract for the next shots
Text descriptions alone do not guarantee identical objects across independent generations. Record the few details that must survive: a red bicycle, a natural wicker basket, a small blue parcel with plain wrapping, and a cream doorway opening inward. Keep them consistent in subsequent prompts.
Shot B can be simpler than Shot A:
Close view of a small plain blue parcel resting inside the wicker front basket of a red delivery bicycle. The parcel settles slightly as the bicycle becomes still. Soft overcast morning light, muted blue shop wall in the background, steady camera, shallow but readable depth of field, continuous realistic shot.
Shot C changes the subject of attention:
Medium view of a cream shop door beside a muted blue exterior wall. The door slowly opens inward, revealing a softly lit uncluttered repair shop. The edge of a red bicycle basket with a blue parcel remains visible in the lower left foreground. Stationary camera at standing eye level, soft morning light, one calm continuous shot.
If the interface supports suitable reference inputs, use approved references according to that mode's documentation. Do not assume a seed will preserve a character or object across different models. When continuity is crucial and the reference route is unavailable, change the edit: an insert of the parcel can bridge two wider shots without demanding a perfect repeated face. A character consistency checklist makes these dependencies explicit.
Iterate by naming the missing relationship
Imagine Shot A shows a floating bicycle instead of wheels touching the ground. The correction should address contact and reduce complexity. Try a bicycle already standing beside the door with its basket gently settling. You lose the arrival action, but preserve the story information with a more manageable task.
If the parcel disappears, make it a prominent foreground subject or move its important reveal to Shot B. Asking for more detail everywhere does not necessarily increase the visibility of the one object carrying the story. Decide which shot owns that information.
If Shot C opens the door outward, check whether the direction matters to the edit. When it does, rewrite only that action and keep the rest fixed. If it does not, record the accepted change and align neighboring shots. Production sometimes improves by adjusting a nonessential plan rather than forcing repeated generations.
Use a small revision log: take number, exact prompt, settings, observed problem, next single change. Keep rejected takes. Without that record, it is easy to compare a new model at a different resolution against an old prompt and incorrectly credit the wording. The Runway vs Kling evaluation explains how to hold a shared brief constant.
Add audio deliberately
Picture and sound are separate decisions even when a model can generate them together. For this sequence, you might need a wheel rolling, a light basket rattle, and a door hinge. Those sounds can be produced or sourced later. The first visual exercise does not require native dialogue.
If your selected mode supports sound prompting, state the desired sounds clearly and review the downloaded track. Do not assume silence because you omitted audio instructions. A generated voice, unexpected music, or inconsistent ambience can interfere with a narrator.
For dialogue, keep the sentence short enough for its shot and specify who says it. Put the actual words in quotation marks instead of describing “a friendly conversation.” Timing requests are directions rather than frame-accurate guarantees. When the spoken words must be exact, approve the audio first and evaluate a dedicated lip-sync workflow.
Current access also matters. Google's Veo documentation reports that listed Veo 3.1 Preview endpoints in the Gemini API closed on October 22, 2026. Do not copy an old endpoint example into a new production workflow without checking its current availability. That notice concerns those endpoints; it does not establish the status of every platform carrying the Veo name.
Assemble the short in an editor
Place the selected intervals in narrative order before adding transitions. A hard cut from arrival to parcel is often enough. A decorative transition can hide a weak information sequence during review, so judge the cuts plainly first.
Listen to any narration against the actual clip lengths. The parcel insert can absorb a pause or hide a jump in the voice track. If the door opening is too slow, use only its readable beginning rather than speeding the entire clip until it looks unnatural. Keep normal playback speed as the first option.
Check color and lighting across the sequence. Independent text generations may interpret “morning” differently. A moderate correction can bring shots closer, but large discrepancies in shadow direction or weather are continuity decisions, not simply grading problems. Replace the mismatched shot if the change distracts from the story.
Add text, logos, and captions using editing tools. That gives you exact spelling, stable placement, and an editable file. Keep generated image detail separate from the information that must remain accurate. For a business deliverable, the product-video workflow adds stricter checks for labels and functional claims.
Deliver a reusable production record
A useful handoff includes the short itself, the three selected source clips, the rejected-take notes, and a shot list showing the final order. State which materials were generated and which were recorded or added in editing. Save any input references with their usage permissions.
Before calling it complete, watch the exported file from beginning to end at the size viewers will actually see. Confirm the first frame is intentional, the parcel is identifiable, and the closing image does not freeze accidentally. Check the audio on a second playback and verify captions against the final words.
Text to video AI becomes more manageable when you judge a small visible event rather than an entire imagined film. The three-shot exercise gives you an arrival, a meaningful object, and a change of state. Once those relationships work, you can expand the story using an episode outline instead of adding unrelated instructions to a single generation.